Blog

Server CPU Trend Analysis: Find Linux Performance Drift Early

Server CPU Trend Analysis: Find Linux Performance Drift Early

Nov 15, 2026    Mariusz Antonik    Automation    9 min read

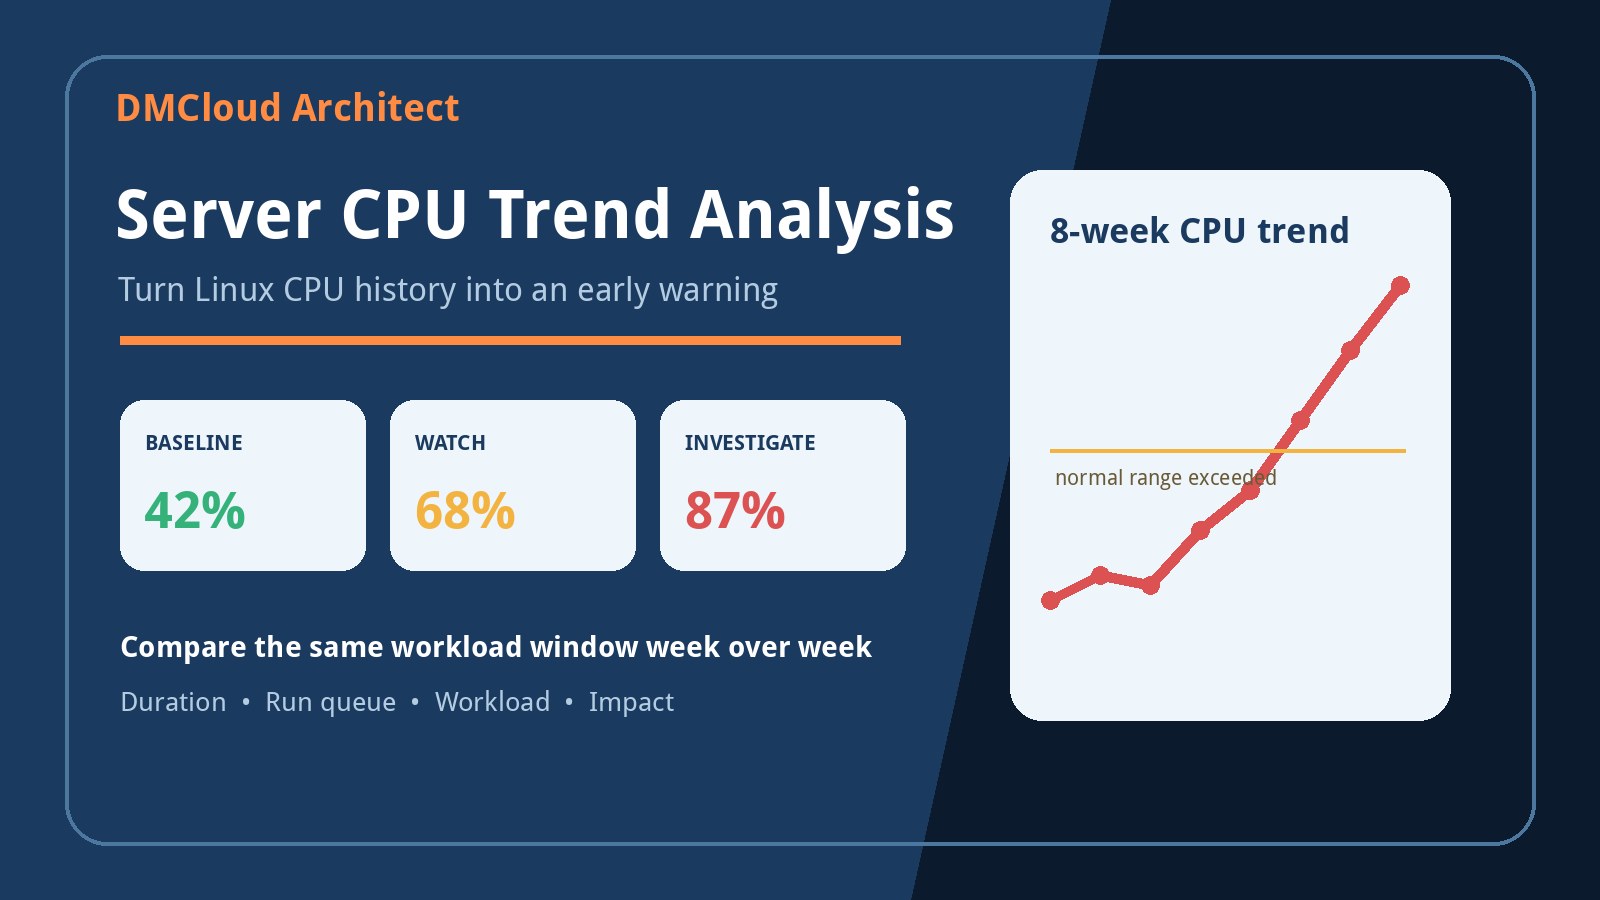
Server CPU trend analysis reveals gradual Linux performance drift that a one-time utilization snapshot cannot show. A useful review compares consistent workload windows, duration, run-queue demand, process activity, and service impact against a reliable baseline. This guide explains how to collect CPU history, interpret the trend, and turn it into practical weekly decisions before users notice a slowdown.

Read More
Linux Server Monitoring: A Practical Small-Business Operations Checklist

Linux Server Monitoring: A Practical Small-Business Operations Checklist

Nov 14, 2026    Mariusz Antonik    Automation    8 min read

Reliable Linux server monitoring is more than watching CPU and memory charts. Small businesses need a repeatable operating checklist that connects system health, security, backups, incident response, and recovery readiness. This guide explains what to inspect, which evidence to retain, and how to turn technical findings into clear actions. Use it to build dependable infrastructure oversight without adding another dashboard to watch all day.

Read More
Track Disk Usage Over Time on Linux Before Capacity Becomes an Incident

Track Disk Usage Over Time on Linux Before Capacity Becomes an Incident

Nov 13, 2026    Mariusz Antonik    Automation    7 min read

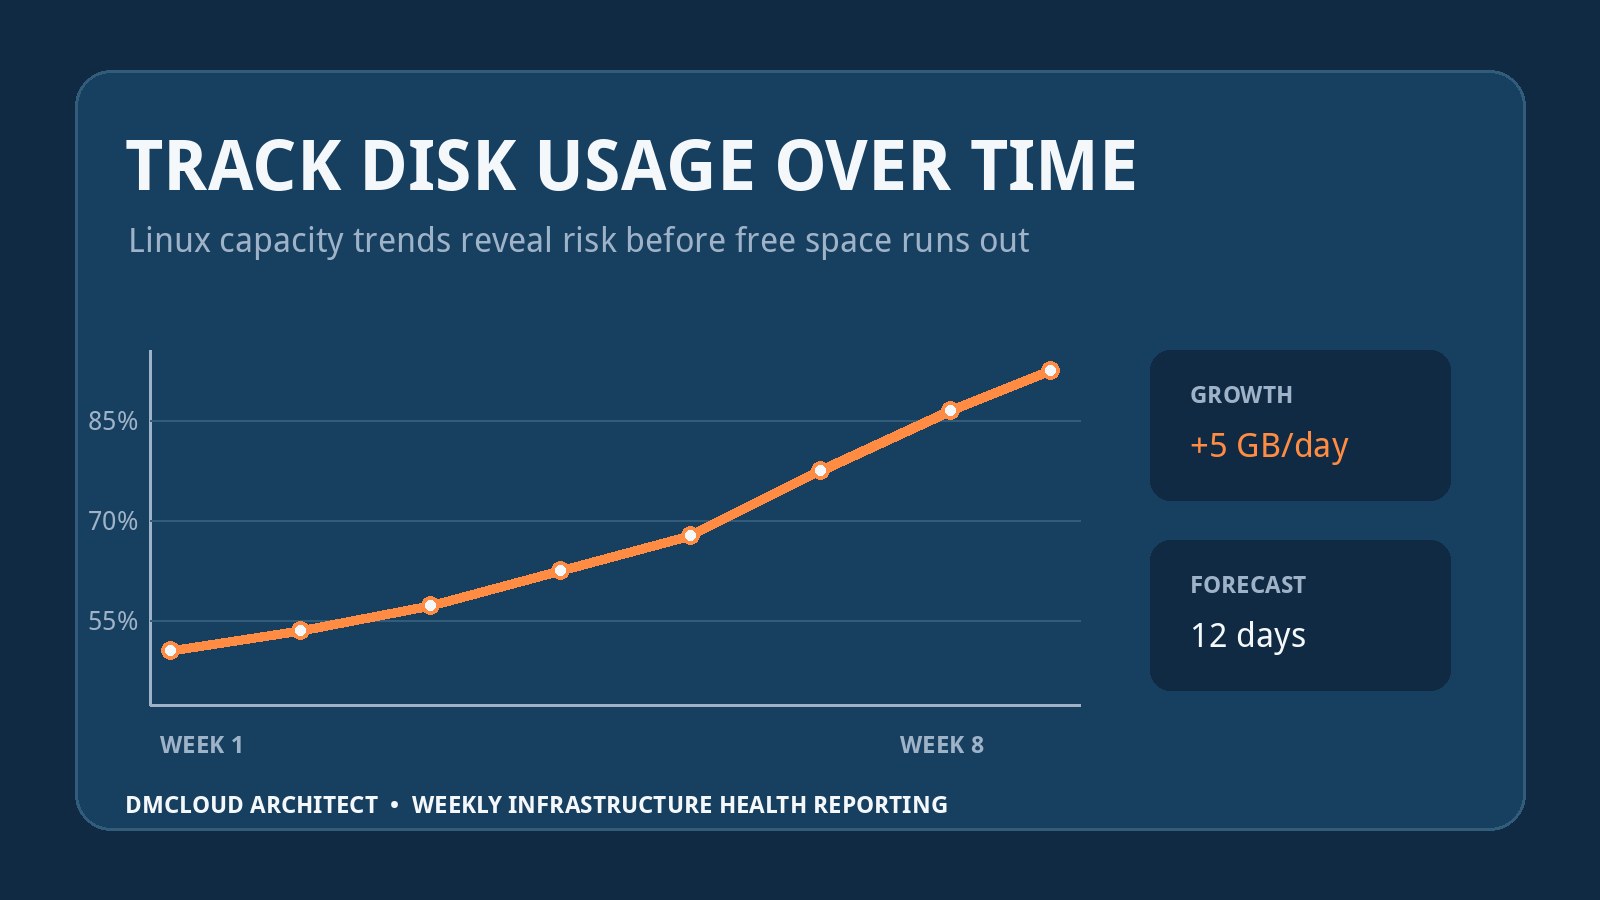
Tracking disk usage over time on Linux reveals capacity risk that a one-off free-space check cannot show. A small history of filesystem utilization, growth rate, and workload context lets you estimate when space may run out and investigate abnormal growth early. This guide presents a lightweight collection method, practical commands, and a weekly reporting approach for developers and small business owners.

Read More
Clonezilla LUKS2 Backup Repositories: A Weekly Capacity Checklist

Clonezilla LUKS2 Backup Repositories: A Weekly Capacity Checklist

Nov 12, 2026    Mariusz Antonik    Automation    10 min read

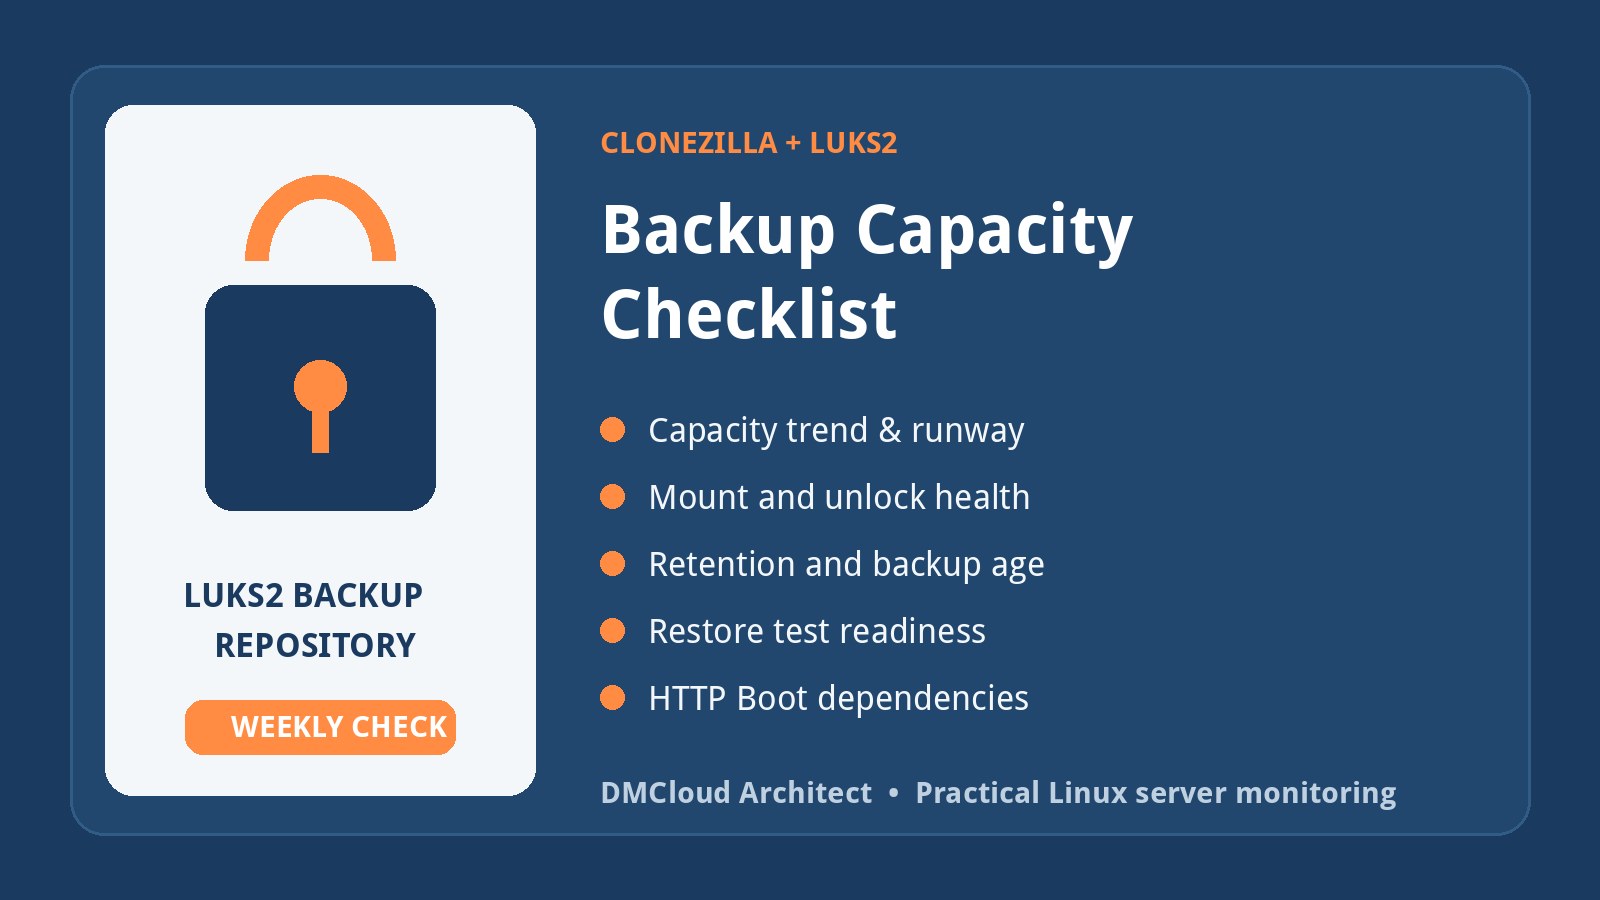
Encrypted image repositories make bare-metal recovery safer, but encryption does not protect them from capacity drift, failed mounts, or incomplete retention. This practical checklist shows how to monitor LUKS2-backed Clonezilla storage, estimate growth, verify usable backups, and preserve recovery headroom. It also covers HTTP Boot infrastructure and the operational checks that matter after a deployment-tool upgrade. Use it as a focused Linux server monitoring routine for imaging environments without adding another dashboard.

Read More
CPU Bottleneck Reporting on Linux: Detect Degradation Early

CPU Bottleneck Reporting on Linux: Detect Degradation Early

Nov 11, 2026    Mariusz Antonik    Automation    8 min read

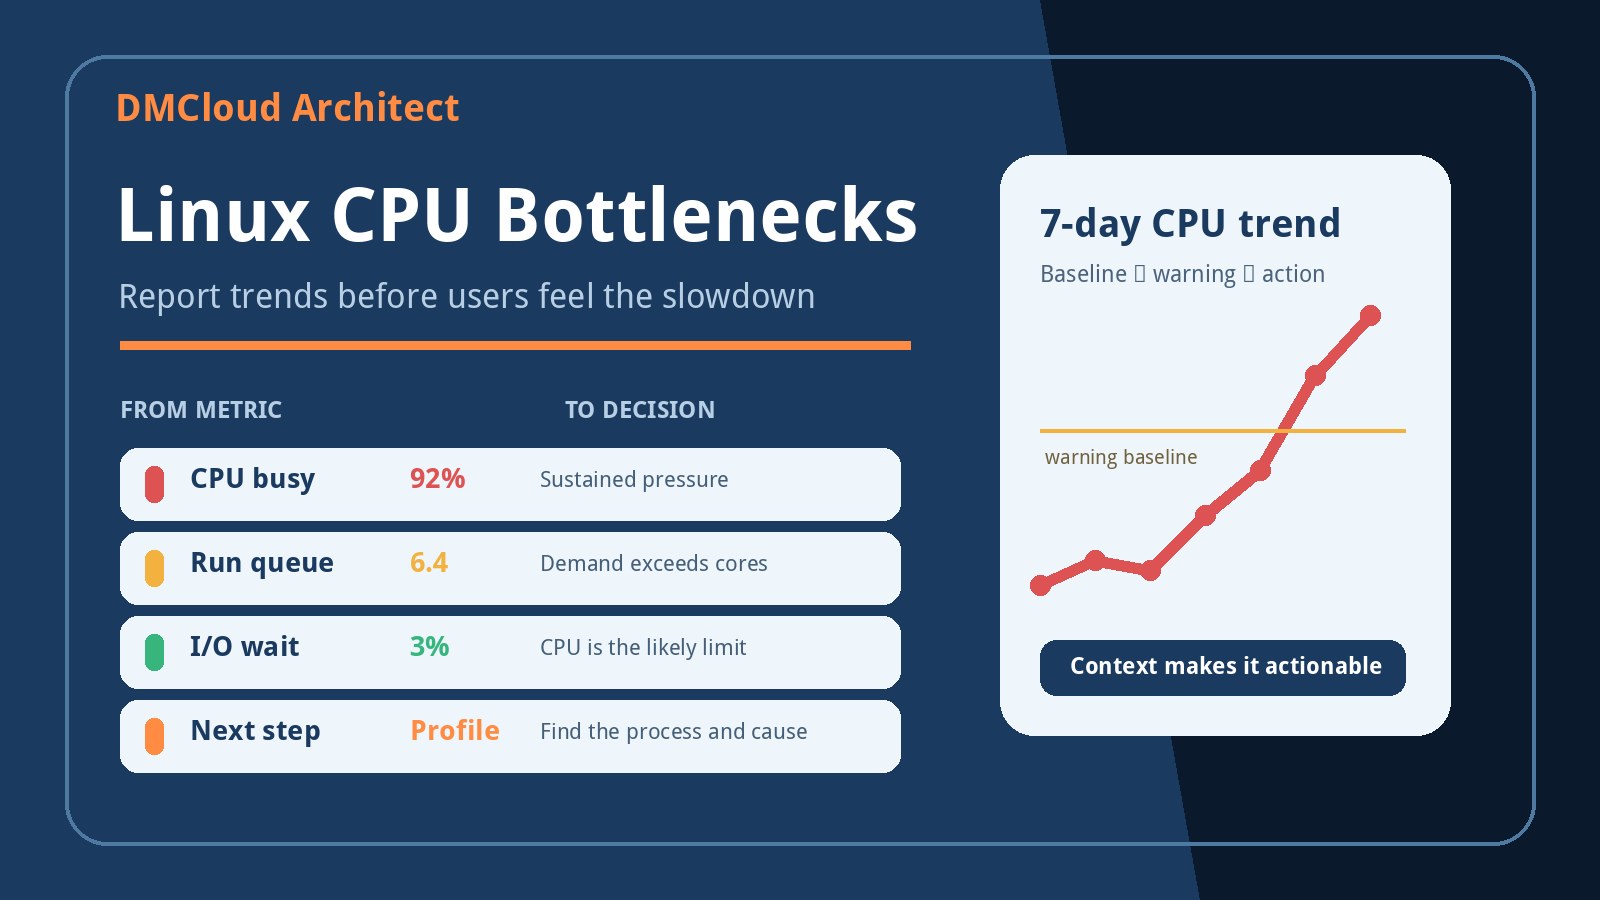
CPU bottleneck reporting on Linux should explain sustained pressure, not merely list a high utilization percentage. Combining CPU time, run-queue demand, load, process data, and workload context helps teams distinguish real saturation from harmless bursts. This guide shows how to build a concise report that detects degradation early and ends with a practical next action.

Read More
Disk Growth Warning Signs: A Weekly Linux Server Checklist

Disk Growth Warning Signs: A Weekly Linux Server Checklist

Nov 10, 2026    Mariusz Antonik    Automation    9 min read

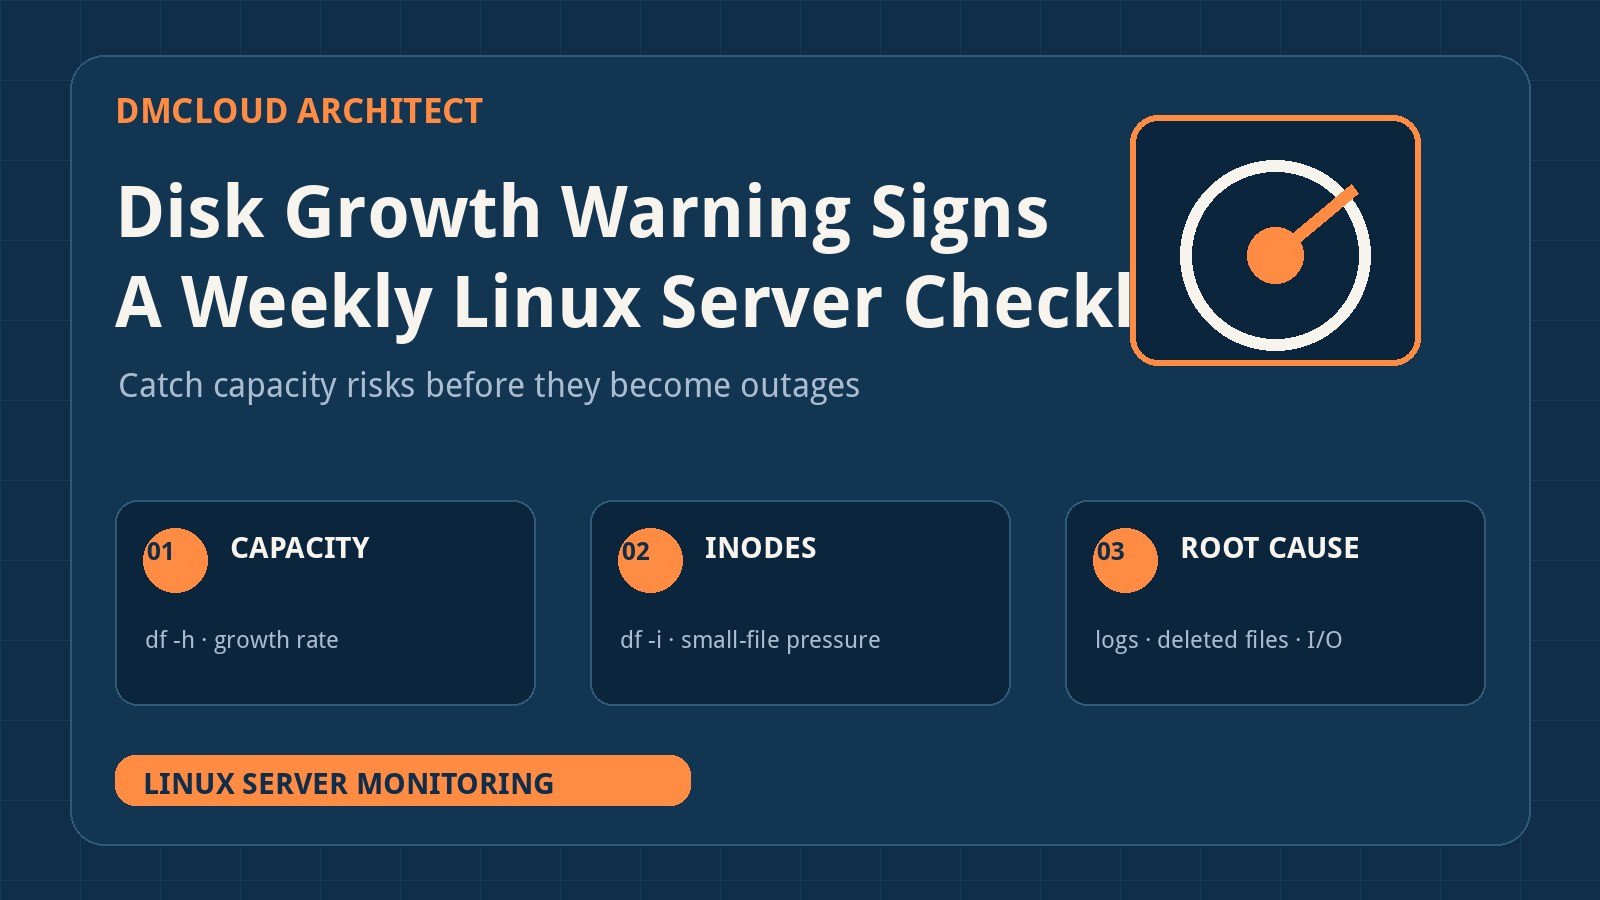
Disk incidents rarely begin with a completely full filesystem; they begin with a trend that nobody reviews. This weekly Linux server checklist shows how to check capacity, inode use, log growth, deleted-open files, and high-I/O processes before they cause downtime. It also explains which warning signs need immediate action and which belong in a measured cleanup plan. Use it as a lightweight Linux server monitoring routine for small fleets without adding another dashboard.

Read More
MySQL Health Check: A Practical Weekly Checklist

MySQL Health Check: A Practical Weekly Checklist

Nov 09, 2026    Mariusz Antonik    Database    8 min read

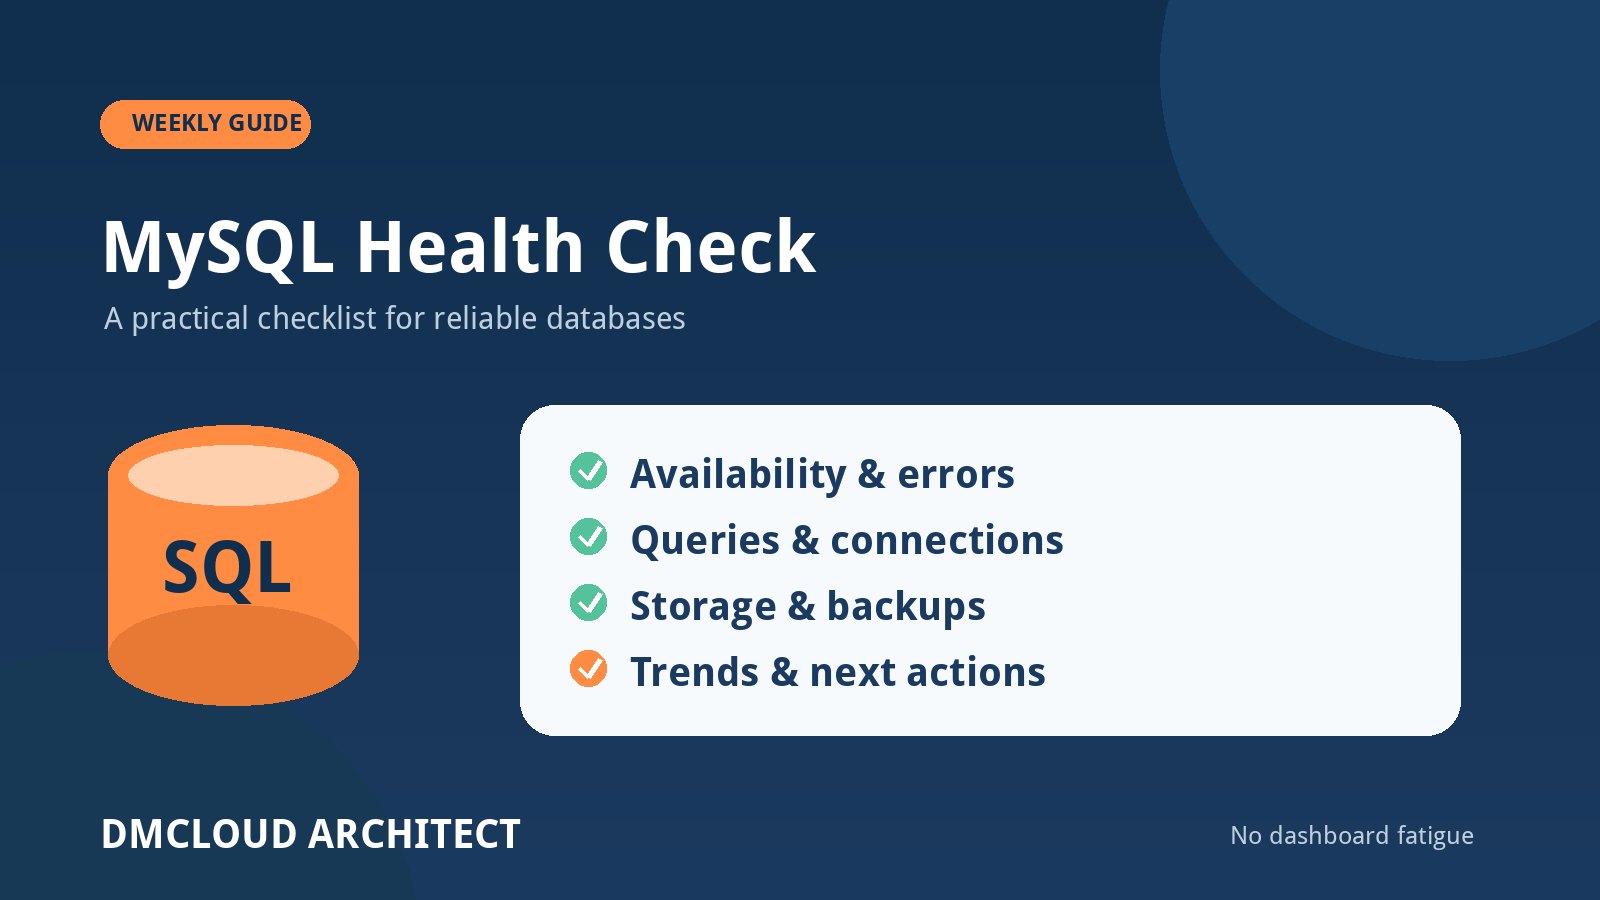
A MySQL health check should confirm more than whether the database service is running. A short weekly review of availability, connections, query performance, storage, backups, and recent changes can expose gradual risk before users notice it. This checklist gives developers and small teams a repeatable way to assess MySQL health without living in a monitoring dashboard.

Read More
CVE-2026-98432 Linux Server Checklist: Check, Patch, and Verify

CVE-2026-98432 Linux Server Checklist: Check, Patch, and Verify

Nov 08, 2026    Mariusz Antonik    Security    8 min read

CVE-2026-98432 is a critical Linux kernel IPv4 TCP use-after-free vulnerability that deserves prompt review on internet-facing servers. This checklist shows how to inventory exposure, check the running kernel and MPTCP state, follow distribution-specific advisories, patch safely, reboot, and verify the result. It separates confirmed vendor information from unverified scanning reports and treats temporary mitigations as risk reduction rather than a replacement for updates. It also shows how Linux server monitoring can confirm that remediation remains in place across a small fleet.

Read More
MySQL Performance Visibility: Turn Metrics into Useful Trends

MySQL Performance Visibility: Turn Metrics into Useful Trends

Nov 07, 2026    Mariusz Antonik    Database    8 min read

MySQL performance visibility comes from comparing a small set of reliable measurements over time, not collecting every available counter. A useful trend view connects workload, latency, connections, resource pressure, and database changes so gradual degradation becomes visible before users complain. This guide shows developers and small teams what to measure, how to build a baseline, and how to turn weekly trends into practical actions.

Read More
Is Your First Technical Support Job a Dead End? A Linux-to-DevOps Growth Checklist

Is Your First Technical Support Job a Dead End? A Linux-to-DevOps Growth Checklist

Nov 06, 2026    Mariusz Antonik    Automation    9 min read

A first technical support job does not have to match your final career goal to be useful. Monitoring servers, maintaining databases, documenting incidents, and administering software can become credible Linux and DevOps experience when you deliberately build depth and evidence. This checklist helps you judge whether the role is still teaching you, identify warning signs, and create a practical 90-day growth plan. It also explains how to turn Linux server monitoring work into portfolio and interview material without exaggerating your responsibilities.

Read More