Blog

Linux Server Health Checks: A Practical Weekly Checklist

Linux Server Health Checks: A Practical Weekly Checklist

Oct 18, 2026    Mariusz Antonik    Automation    8 min read

Linux server health checks help small teams find capacity, service, storage, and backup risks before users report a problem. This practical weekly checklist explains what to review, which commands provide useful evidence, and how to compare results over time. It keeps Linux monitoring focused on clear decisions instead of another noisy dashboard.

Read More
Linux AD Machine Password Rotation: A Safe Cleanup Checklist

Linux AD Machine Password Rotation: A Safe Cleanup Checklist

Oct 17, 2026    Mariusz Antonik    Security    8 min read

A Linux computer account can show PasswordNeverExpires in Active Directory even while SSSD is successfully rotating its machine password. This checklist explains how to separate an AD attribute finding from actual keytab health, trace why the flag is still being set, and clear it safely at scale. It also shows which evidence belongs in practical Linux server monitoring so the same drift does not return unnoticed.

Read More
Infrastructure Trend Visibility: Spot Server Risk Before It Becomes an Incident

Infrastructure Trend Visibility: Spot Server Risk Before It Becomes an Incident

Oct 16, 2026    Mariusz Antonik    Automation    7 min read

Infrastructure trend visibility helps small teams catch slow-moving server risks before they become outages. This practical guide explains which Linux, database, storage, and backup trends deserve attention and how to compare them without dashboard fatigue. Learn how a short weekly review can turn historical monitoring data into clear, timely action.

Read More
Unified Linux Server Monitoring: A Practical Tool Evaluation Checklist

Unified Linux Server Monitoring: A Practical Tool Evaluation Checklist

Oct 15, 2026    Mariusz Antonik    Automation    9 min read

A unified Linux monitoring tool can simplify operations, but only if it turns host data into reliable decisions instead of another noisy dashboard. This practical checklist helps developers and small business owners assess collection coverage, service health, alert quality, security, remote management, and reporting. It also explains when a focused weekly health report is more useful than expanding a real-time monitoring stack.

Read More
MySQL Monitoring in Production: A Practical Weekly Checklist

MySQL Monitoring in Production: A Practical Weekly Checklist

Oct 14, 2026    Mariusz Antonik    Database    6 min read

MySQL monitoring in production should make database risk easy to see before customers notice slow pages or failed jobs. This guide covers the weekly checks that matter most: connections, slow queries, replication, storage, backups, and clear next actions. Use it to keep MySQL health reporting practical without adding dashboard fatigue.

Read More
Inventory Monitoring for Linux and Windows: A Practical Small-Team Checklist

Inventory Monitoring for Linux and Windows: A Practical Small-Team Checklist

Oct 13, 2026    Mariusz Antonik    Automation    7 min read

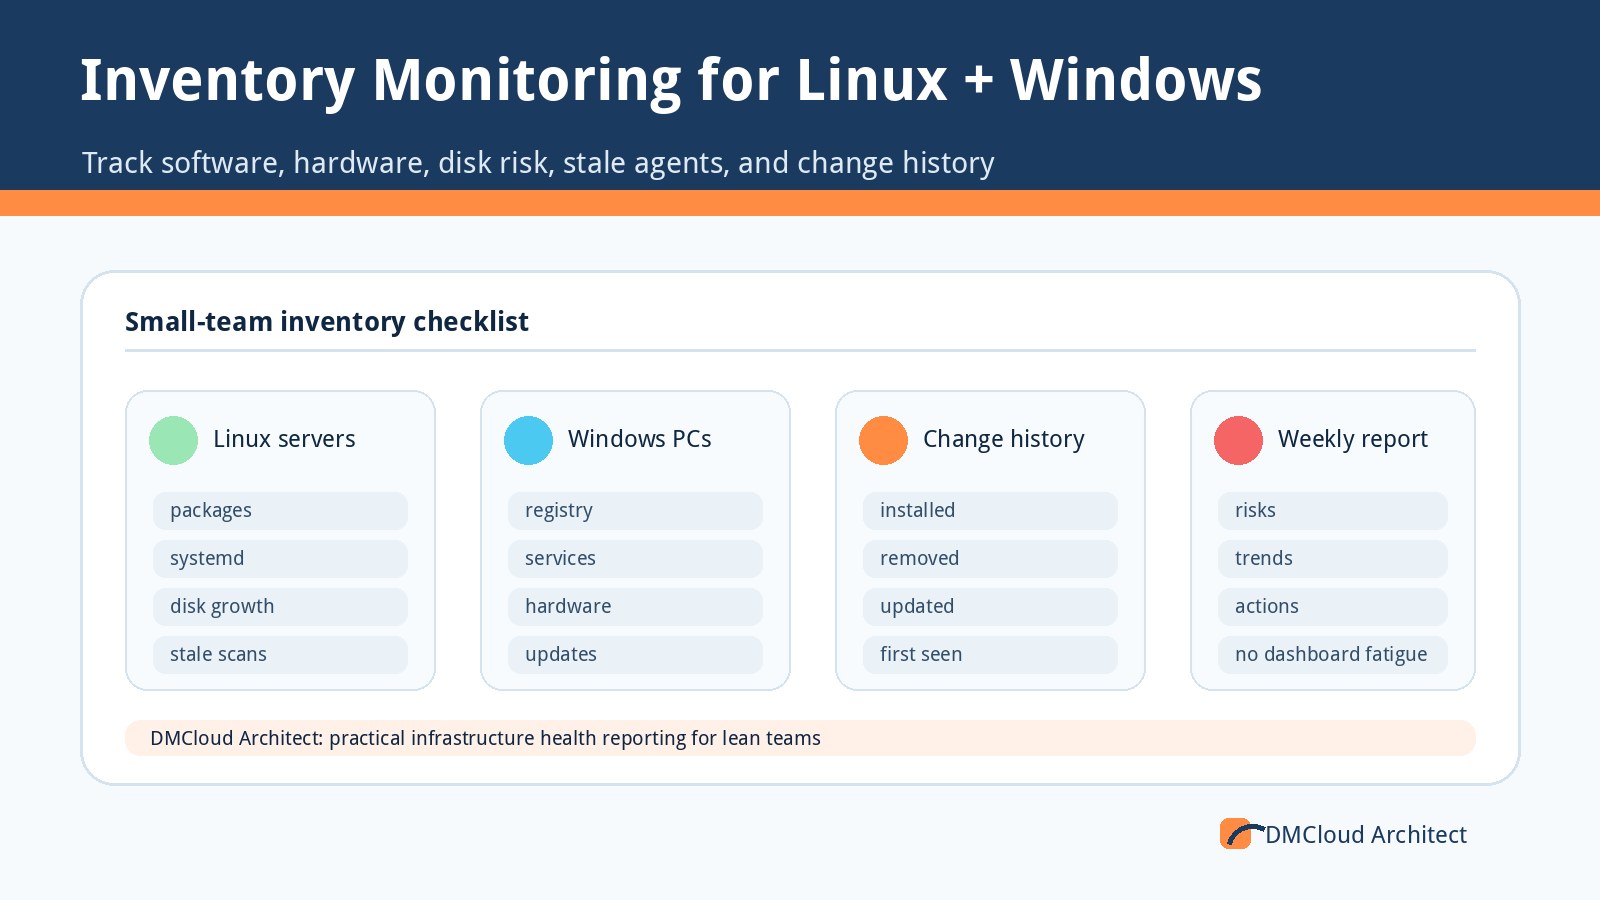
Inventory monitoring is useful only when it helps small teams understand what changed, which machines stopped reporting, and which risks need action. This checklist explains how to evaluate software and hardware tracking across Windows and Linux without turning it into another noisy dashboard. It covers change history, stale agents, disk trends, remote actions, AI categorization, and where weekly infrastructure reports fit beside live monitoring.

Read More
CPU Performance Trends on Linux: Spot Slow Drift Before Users Notice

CPU Performance Trends on Linux: Spot Slow Drift Before Users Notice

Oct 12, 2026    Mariusz Antonik    Automation    5 min read

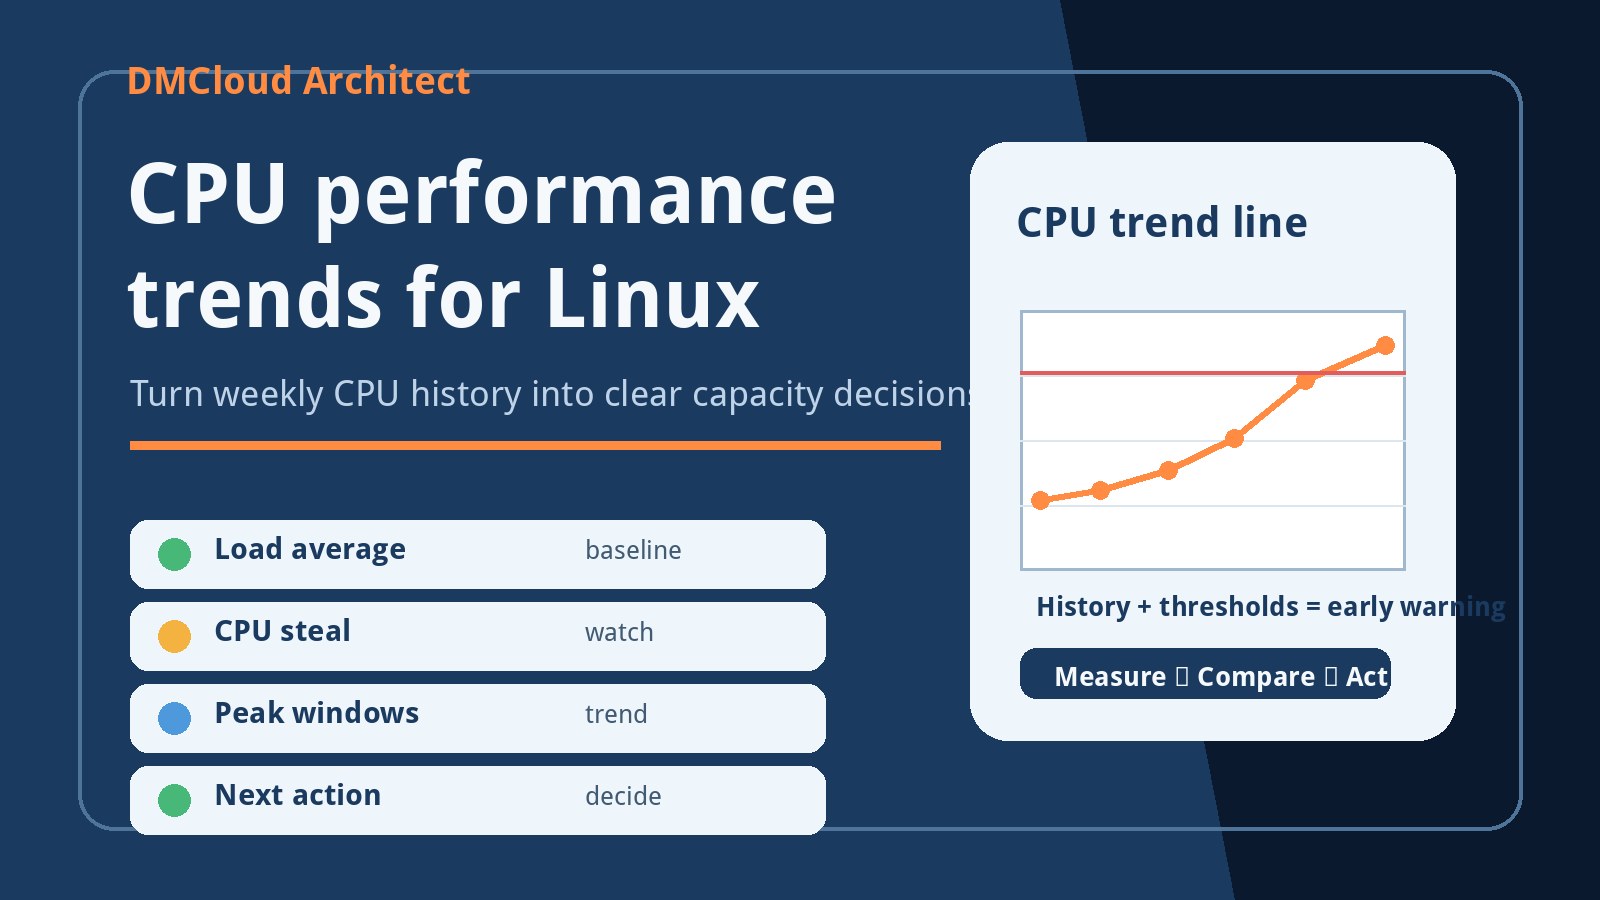
CPU performance trends on Linux show whether a server is quietly moving toward slowdowns before users feel the impact. This guide explains how to track load average, CPU utilization, steal time, and peak windows over time. Use it to turn weekly CPU history into practical capacity decisions without adding dashboard fatigue.

Read More
Linux Time Travel Monitoring: Is It Worth Building? A Practical Checklist

Linux Time Travel Monitoring: Is It Worth Building? A Practical Checklist

Oct 11, 2026    Mariusz Antonik    Automation    7 min read

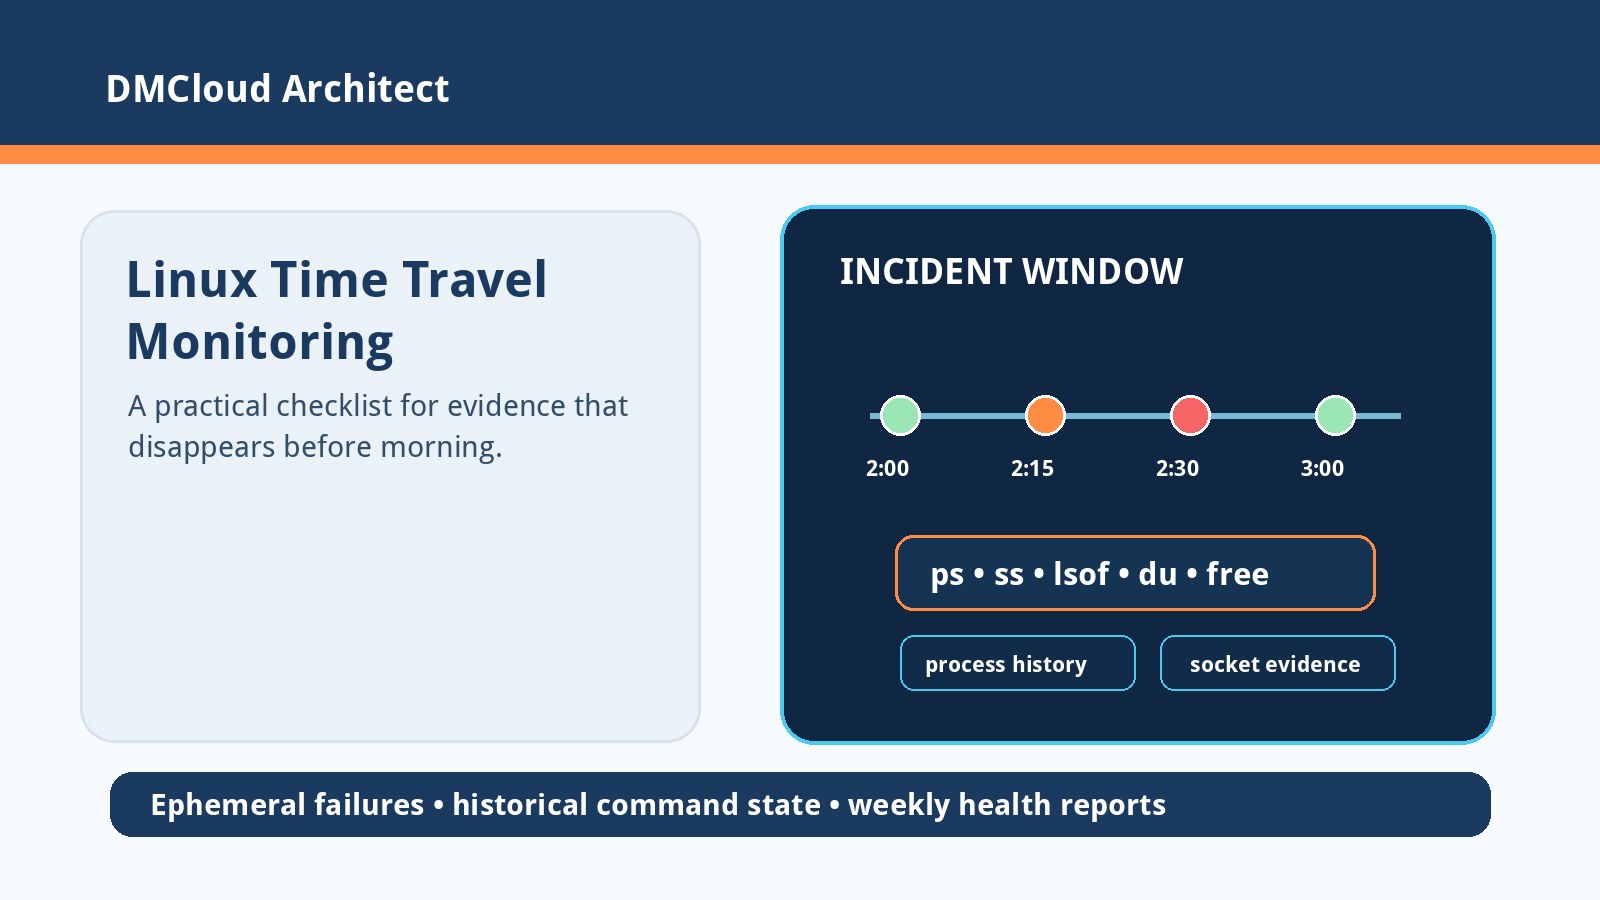
Linux time travel diagnostics can help when the evidence behind an outage disappears before anyone investigates. This checklist compares historical command-state tools with sar, atop, Prometheus, logs, sosreports, auditd, eBPF, and weekly health reports. Use it to decide when a new diagnostic agent is worth building and when better retention or reporting is enough.

Read More
Disk Scaling Planning for Linux: Forecast Capacity Before It Breaks

Disk Scaling Planning for Linux: Forecast Capacity Before It Breaks

Oct 10, 2026    Mariusz Antonik    Automation    5 min read

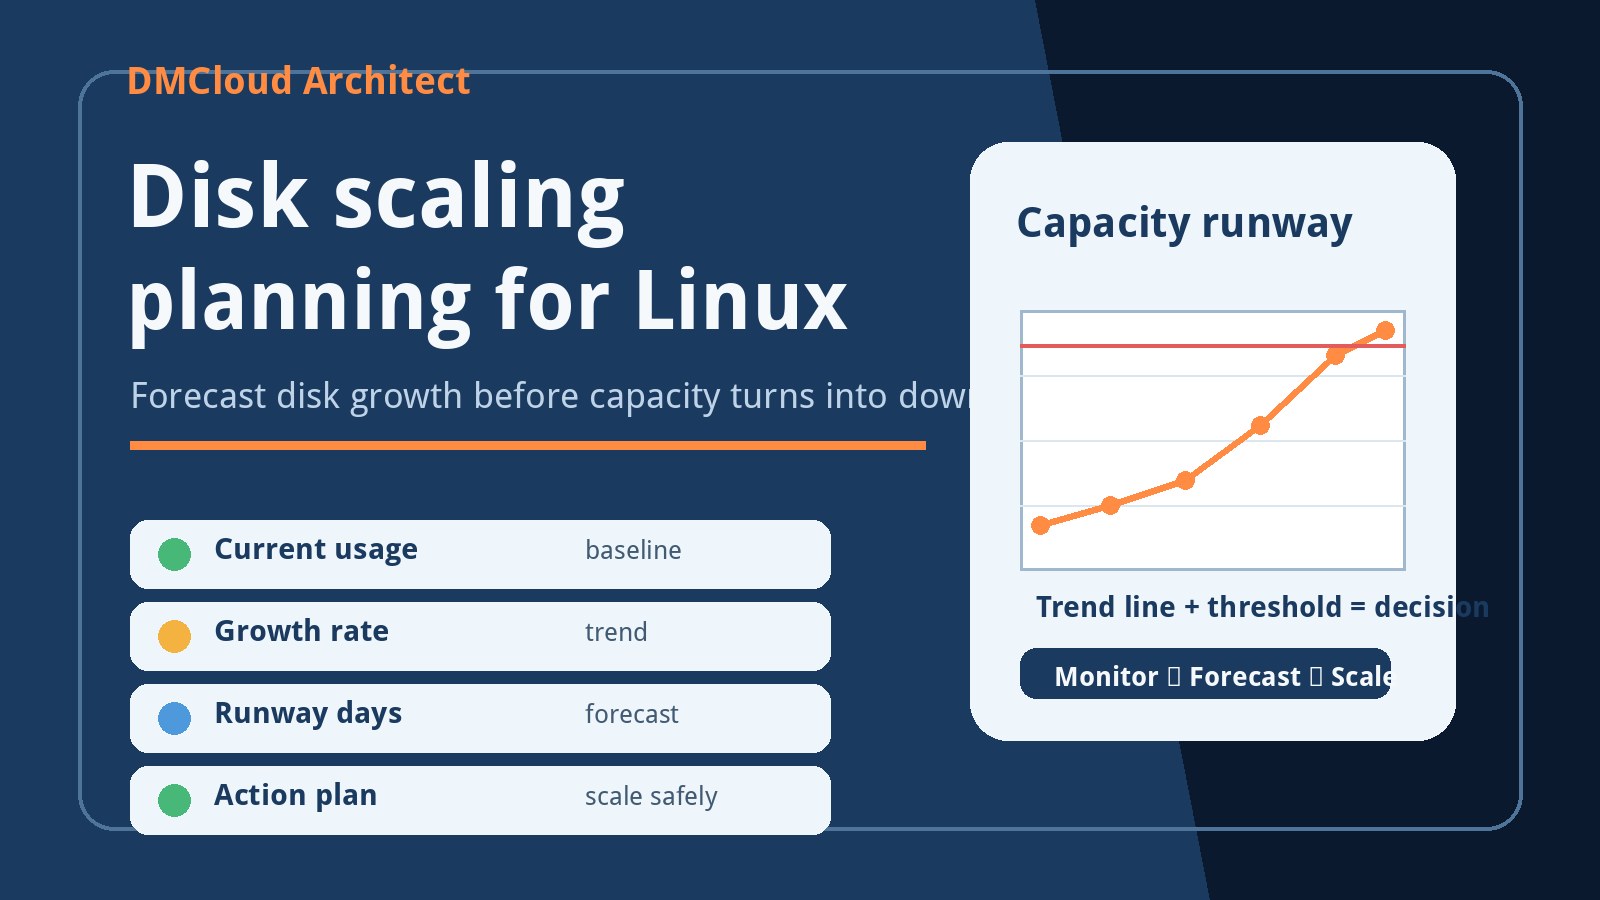
Disk scaling planning for Linux helps small teams move from emergency cleanups to predictable capacity decisions. This guide explains how to baseline disk usage, measure growth, forecast runway, and decide when to archive, resize, or redesign storage. Use it to keep Linux servers healthy without adding another noisy dashboard.

Read More
HPC Cluster Day-2 Operations Checklist for Linux Server Monitoring

HPC Cluster Day-2 Operations Checklist for Linux Server Monitoring

Oct 09, 2026    Mariusz Antonik    Automation    7 min read

HPC cluster administration needs day-2 routines after the first successful OpenHPC build. This checklist covers Linux tuning, InfiniBand health, identity control, Lmod environments, Slurm policy, node health checks, and weekly trend reporting. It gives Linux admins a practical path from home lab cluster to production habits without adding dashboard fatigue.

Read More