Blog - Tag: server health

Simple Disk Monitoring on Linux: A Practical Script and Cron Guide

Simple Disk Monitoring on Linux: A Practical Script and Cron Guide

Nov 19, 2026    Mariusz Antonik    Automation    10 min read

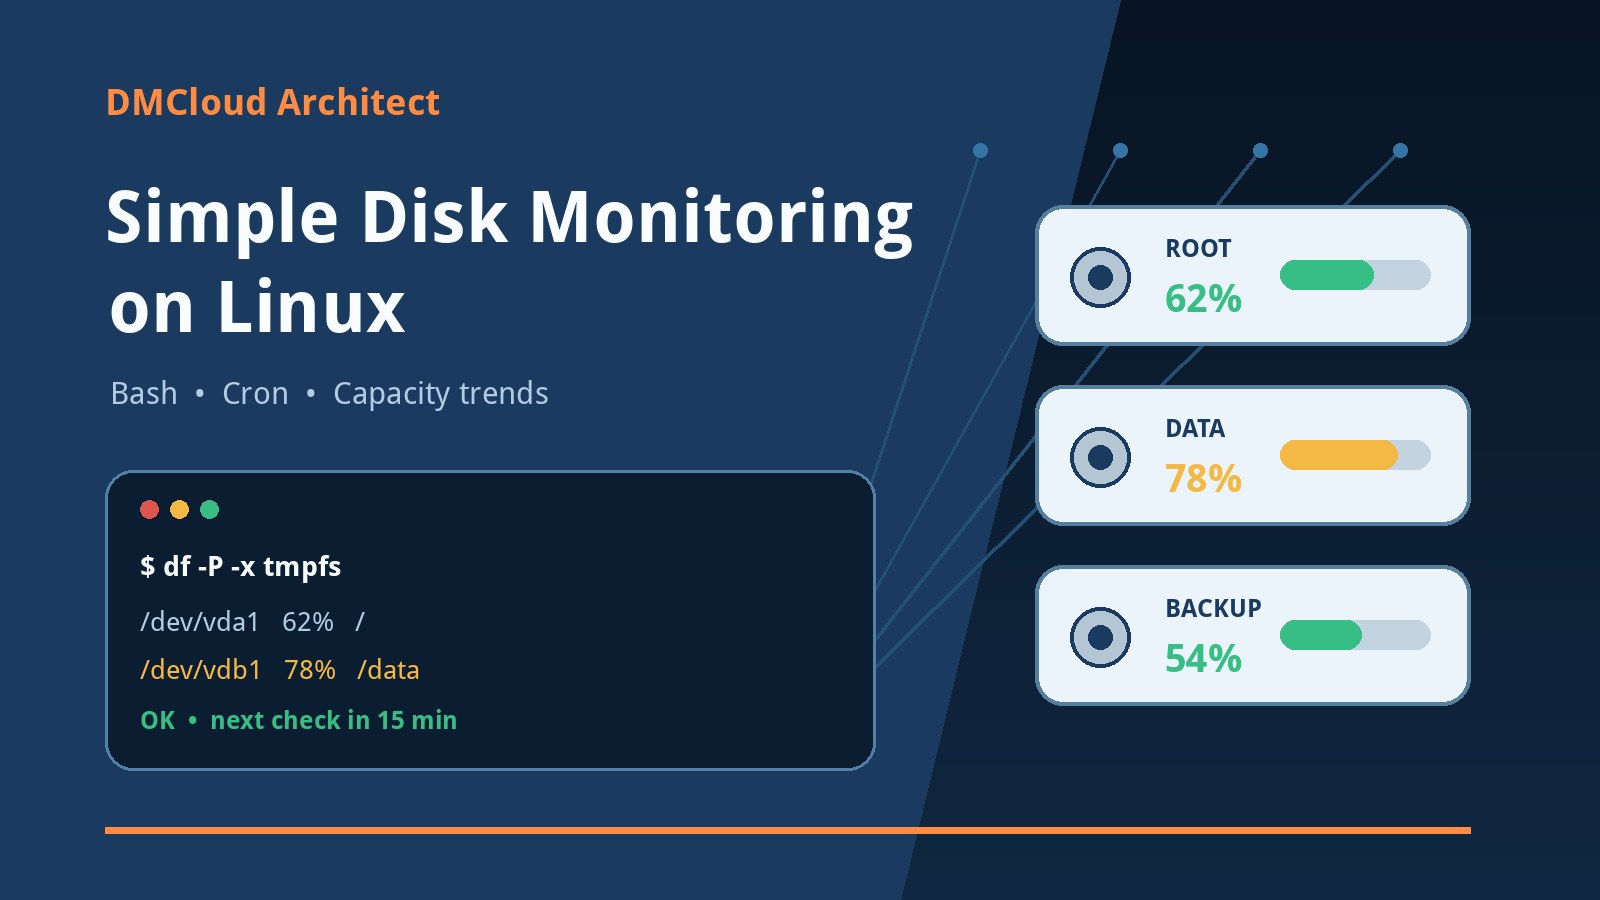
Simple disk monitoring on Linux can catch capacity problems before applications fail, without requiring a large monitoring platform. A dependable setup checks filesystem space and inodes, excludes unsuitable mounts, records timestamped results, and alerts only when action is needed. This guide builds a practical Bash script, schedules it safely with cron, and explains how to turn snapshots into useful trends.

Read More
Server CPU Trend Analysis: Find Linux Performance Drift Early

Server CPU Trend Analysis: Find Linux Performance Drift Early

Nov 15, 2026    Mariusz Antonik    Automation    9 min read

Server CPU trend analysis reveals gradual Linux performance drift that a one-time utilization snapshot cannot show. A useful review compares consistent workload windows, duration, run-queue demand, process activity, and service impact against a reliable baseline. This guide explains how to collect CPU history, interpret the trend, and turn it into practical weekly decisions before users notice a slowdown.

Read More
Linux Server Monitoring: A Practical Small-Business Operations Checklist

Linux Server Monitoring: A Practical Small-Business Operations Checklist

Nov 14, 2026    Mariusz Antonik    Automation    8 min read

Reliable Linux server monitoring is more than watching CPU and memory charts. Small businesses need a repeatable operating checklist that connects system health, security, backups, incident response, and recovery readiness. This guide explains what to inspect, which evidence to retain, and how to turn technical findings into clear actions. Use it to build dependable infrastructure oversight without adding another dashboard to watch all day.

Read More
Track Disk Usage Over Time on Linux Before Capacity Becomes an Incident

Track Disk Usage Over Time on Linux Before Capacity Becomes an Incident

Nov 13, 2026    Mariusz Antonik    Automation    7 min read

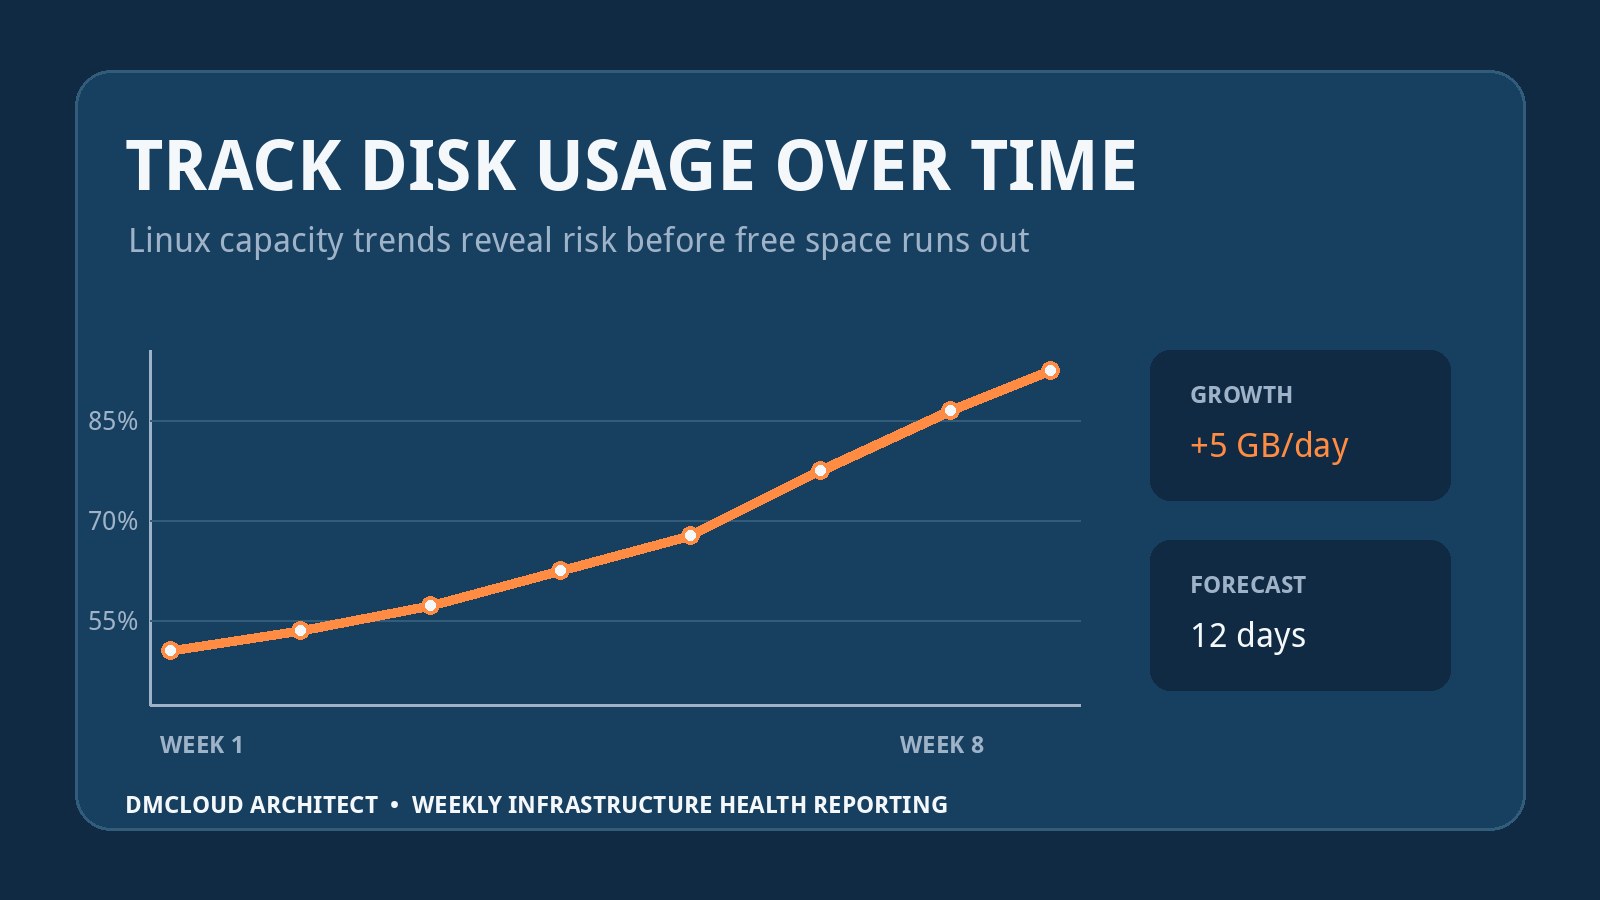
Tracking disk usage over time on Linux reveals capacity risk that a one-off free-space check cannot show. A small history of filesystem utilization, growth rate, and workload context lets you estimate when space may run out and investigate abnormal growth early. This guide presents a lightweight collection method, practical commands, and a weekly reporting approach for developers and small business owners.

Read More
CPU Bottleneck Reporting on Linux: Detect Degradation Early

CPU Bottleneck Reporting on Linux: Detect Degradation Early

Nov 11, 2026    Mariusz Antonik    Automation    8 min read

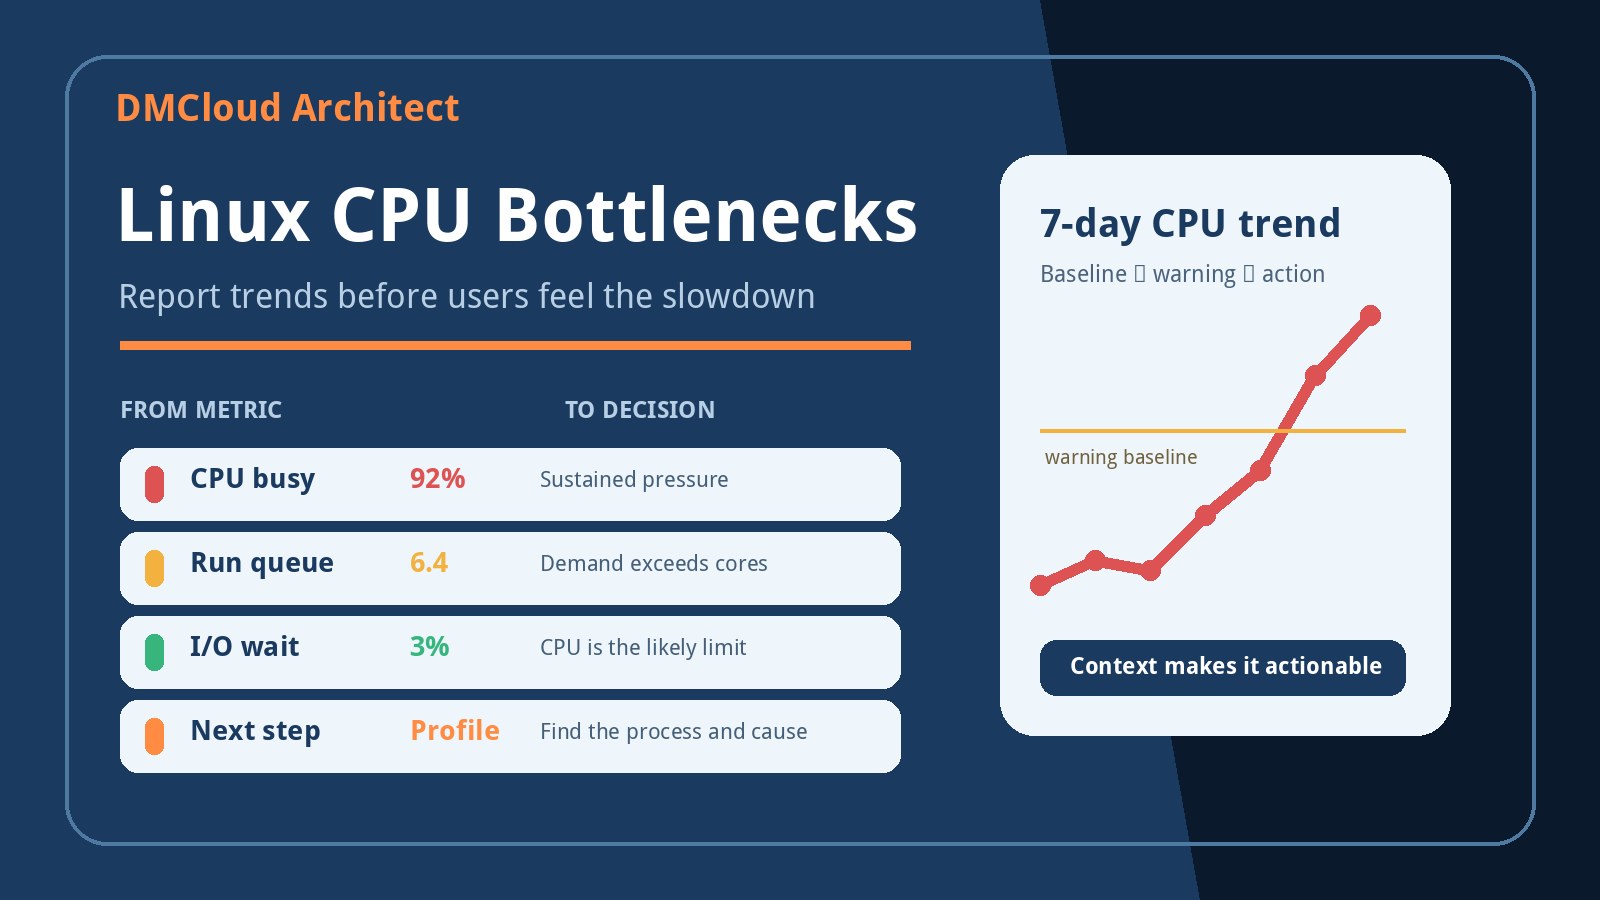
CPU bottleneck reporting on Linux should explain sustained pressure, not merely list a high utilization percentage. Combining CPU time, run-queue demand, load, process data, and workload context helps teams distinguish real saturation from harmless bursts. This guide shows how to build a concise report that detects degradation early and ends with a practical next action.

Read More
CPU Monitoring Commands in Linux: A Practical Guide Without Heavy Tools

CPU Monitoring Commands in Linux: A Practical Guide Without Heavy Tools

Nov 03, 2026    Mariusz Antonik    Automation    9 min read

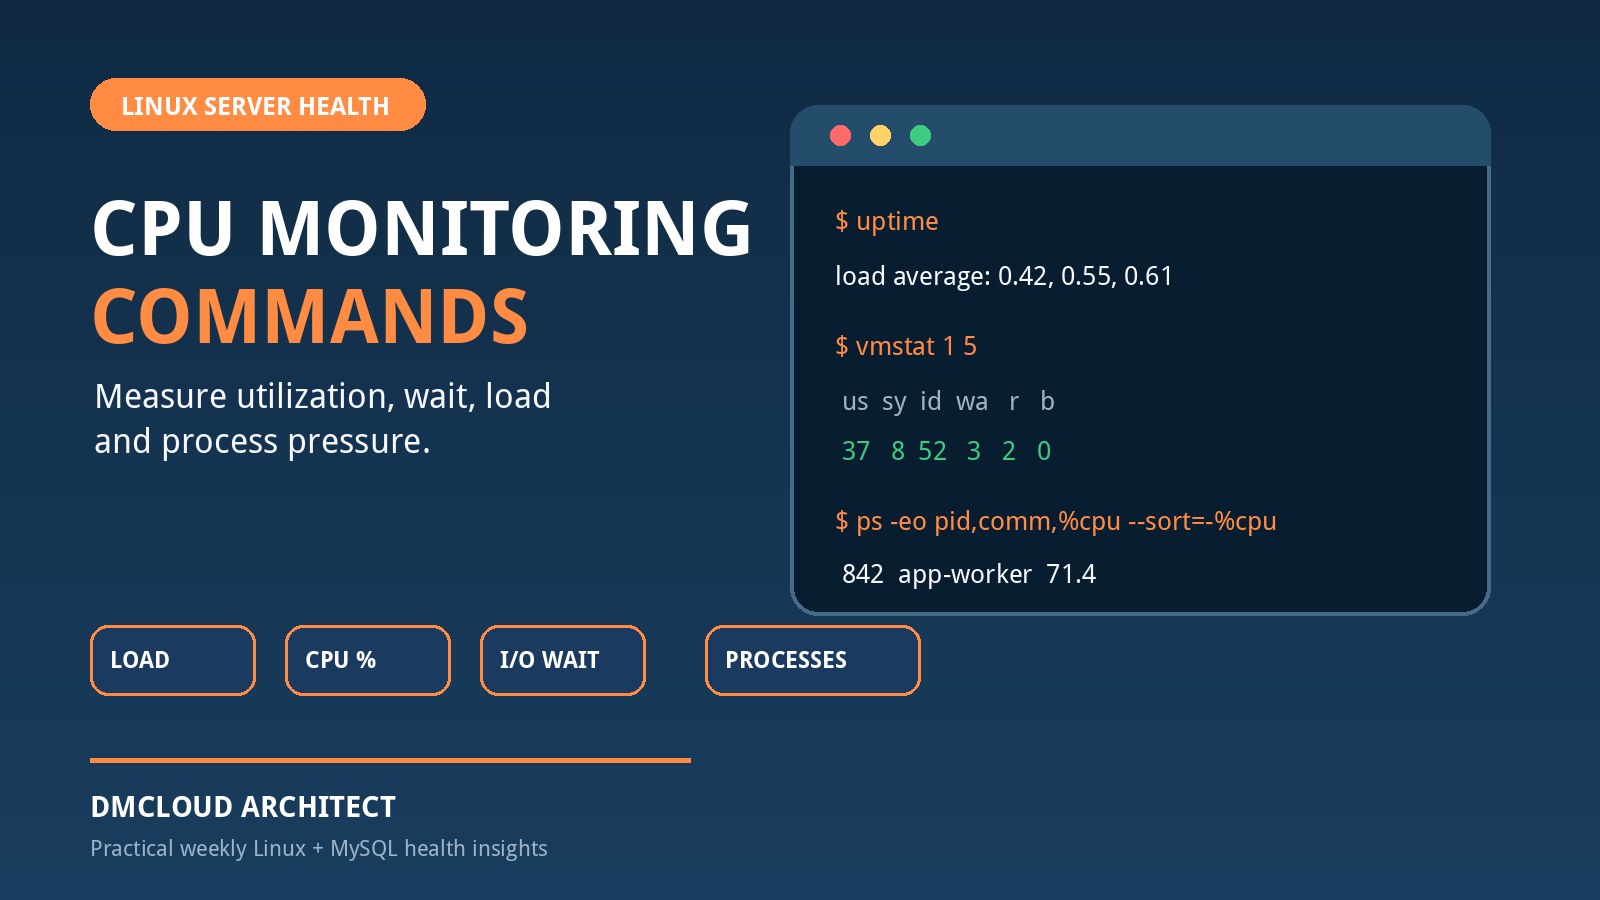
Linux includes enough CPU monitoring commands to diagnose most small-server slowdowns without installing a large observability stack. This guide shows how to read load, utilization, process, wait, and pressure signals with uptime, top, ps, vmstat, mpstat, pidstat, and /proc/stat. It also provides a lightweight Bash sampling pattern and a weekly review workflow for spotting sustained CPU pressure early.

Read More
Baseline-Delta Linux Server Monitoring: Exposure and Process Checklist

Baseline-Delta Linux Server Monitoring: Exposure and Process Checklist

Oct 27, 2026    Mariusz Antonik    Automation    9 min read

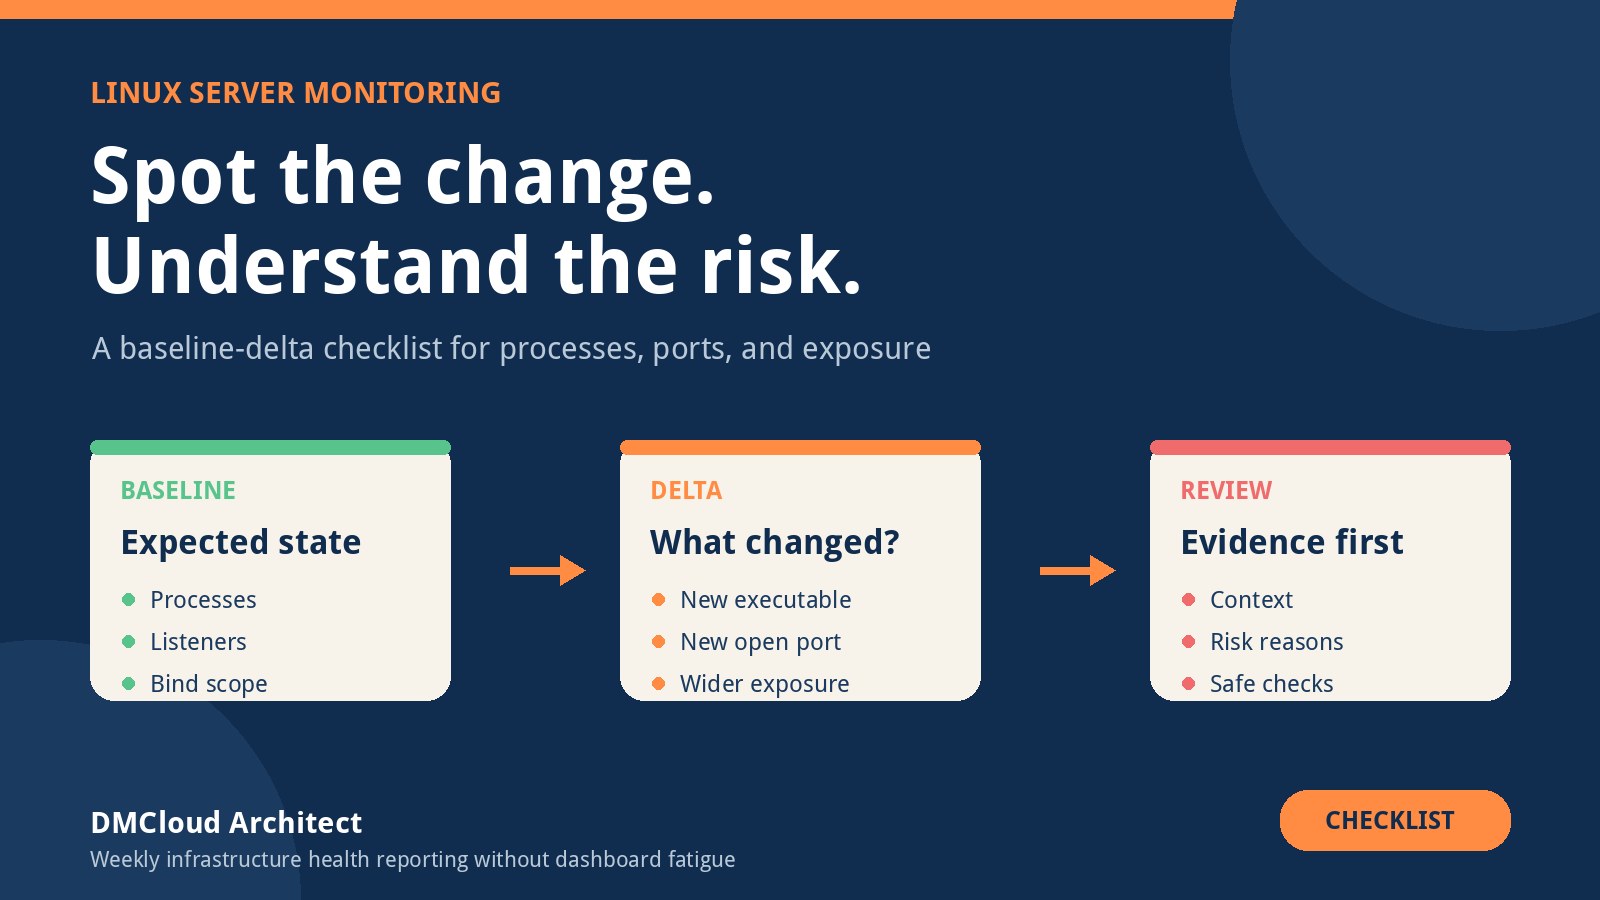
A baseline-delta monitor can reveal newly opened ports, unfamiliar processes, and exposure changes without burying operators in raw logs. This practical checklist explains what to capture, how to classify changes, and how to avoid noisy or misleading alerts. It also shows where real-time change detection, conventional alerts, and weekly health reports each fit.

Read More
Infrastructure Reporting Tools: How to Choose Useful Weekly Reports

Infrastructure Reporting Tools: How to Choose Useful Weekly Reports

Oct 26, 2026    Mariusz Antonik    Automation    9 min read

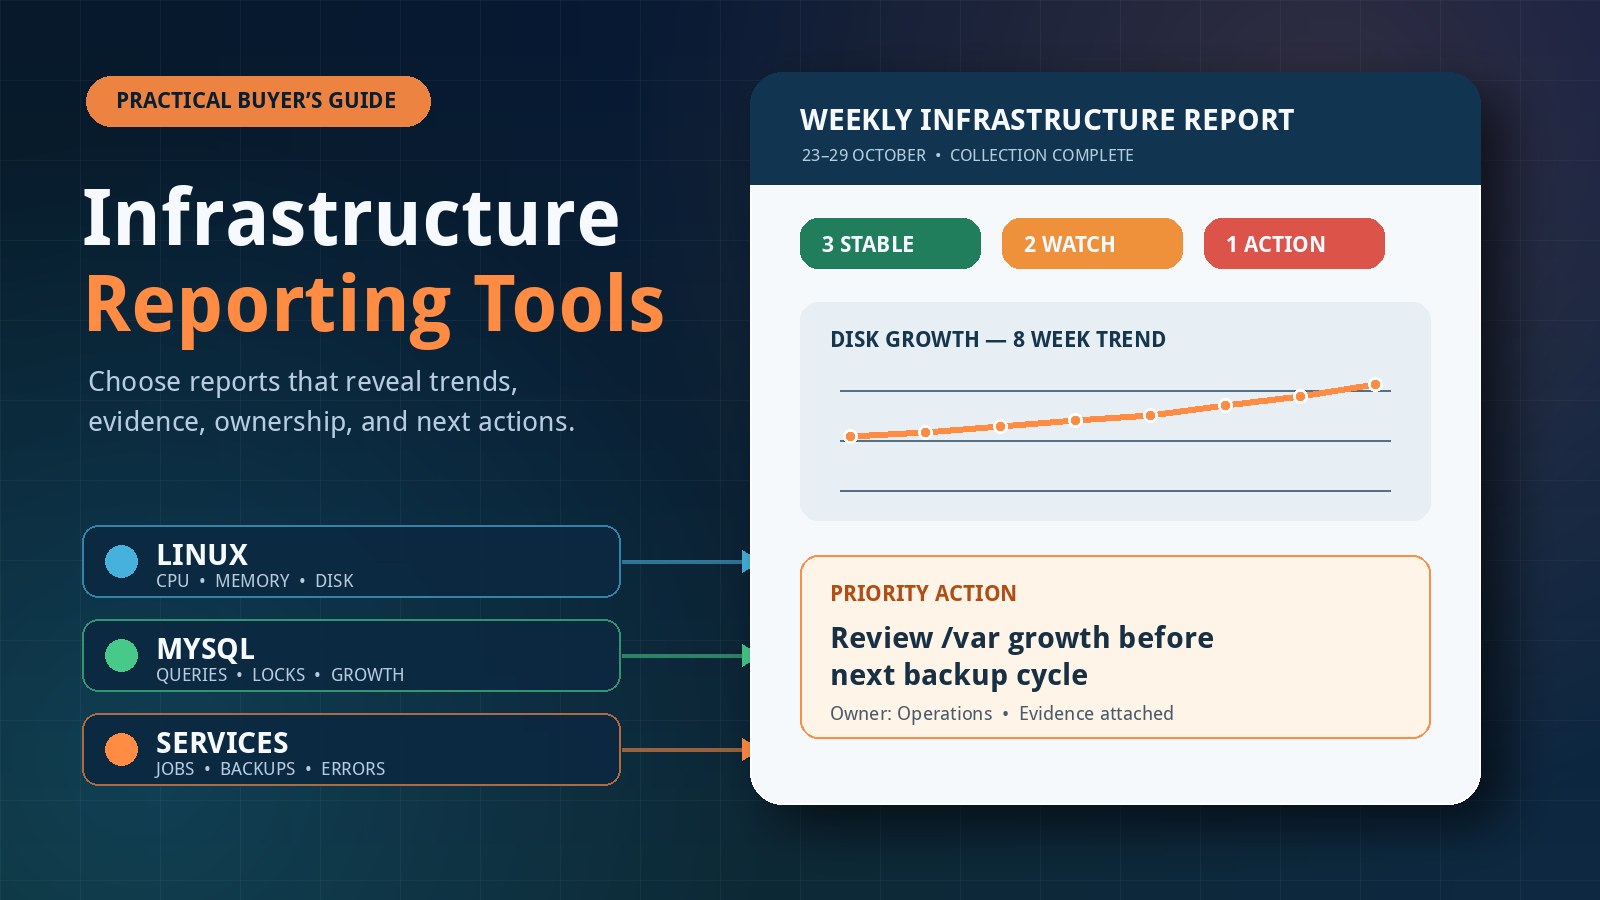
Infrastructure reporting tools turn Linux, database, and service data into evidence a small team can review and act on. This guide explains how reporting differs from monitoring, which signals belong in a useful weekly report, and how to compare products without buying another noisy dashboard. It includes an evaluation scorecard, a practical trial plan, and common warning signs. Use it to choose a reporting workflow that surfaces trends, ownership, and next actions.

Read More
CPU Pressure Detection on Linux: Spot Saturation Before Performance Drops

CPU Pressure Detection on Linux: Spot Saturation Before Performance Drops

Oct 22, 2026    Mariusz Antonik    Automation    8 min read

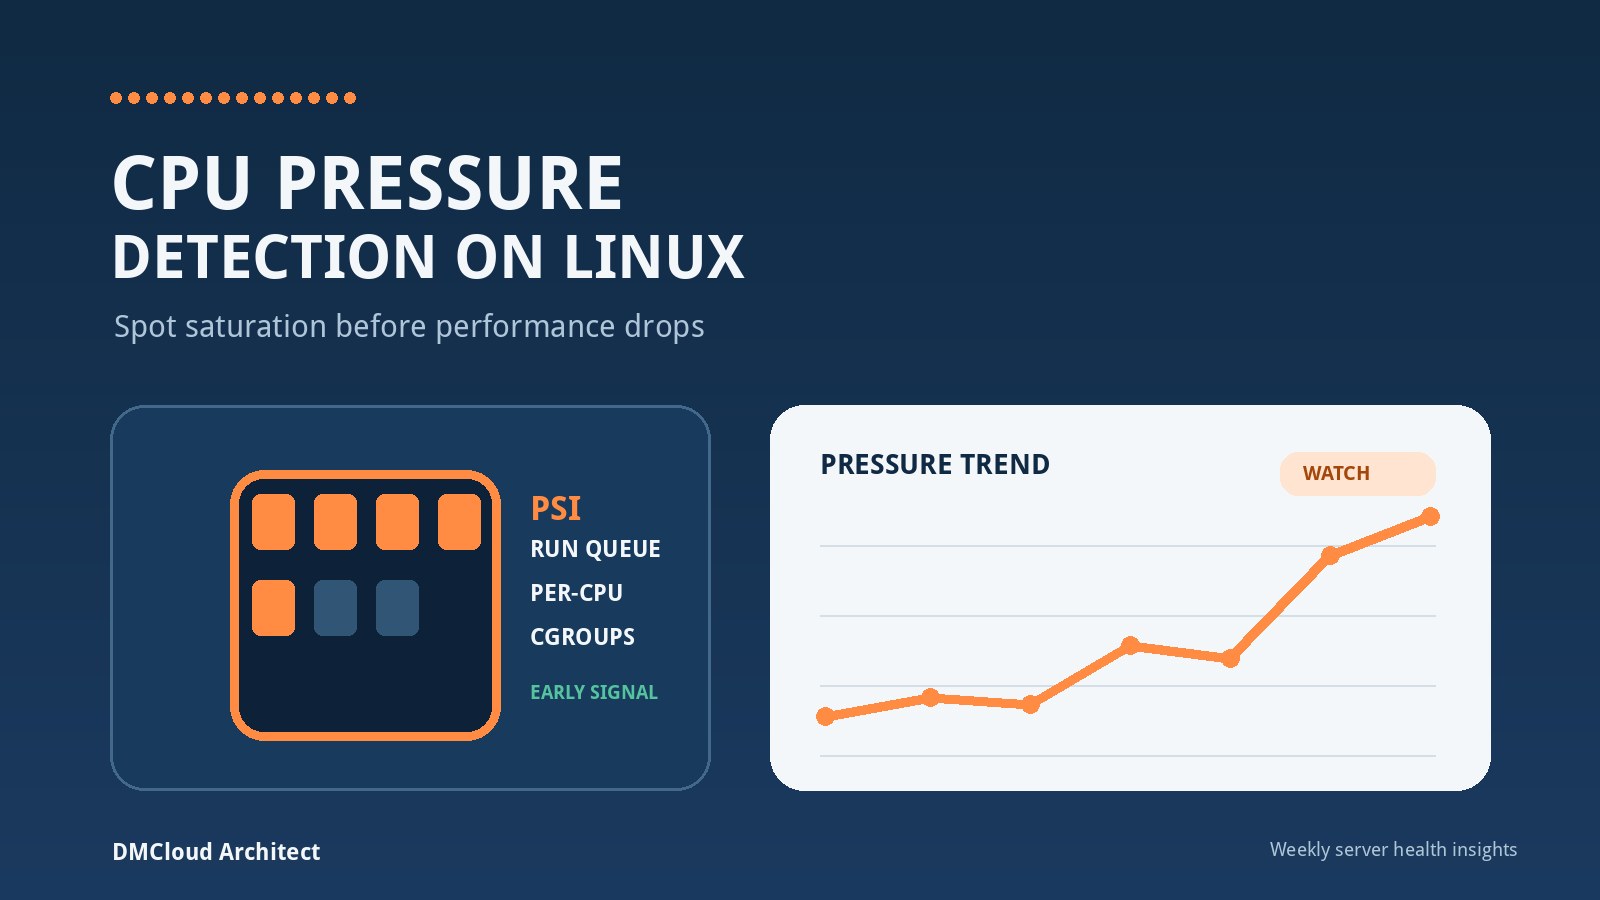
CPU pressure detection on Linux helps distinguish harmless utilization spikes from workloads that are actually waiting for processor time. This guide combines PSI, run-queue, per-CPU, process, and cgroup evidence to identify saturation early. It also shows how small teams can turn recurring samples into practical warning levels and weekly actions.

Read More
Practical Linux Monitoring for Small Teams: A Minimal Weekly System

Practical Linux Monitoring for Small Teams: A Minimal Weekly System

Oct 20, 2026    Mariusz Antonik    Automation    9 min read

Practical Linux monitoring gives small teams enough evidence to spot risk without maintaining a complex observability stack. This guide builds a minimal weekly system around availability, capacity, services, logs, security, and recovery checks. It also shows how to turn command output into trends and clear actions instead of dashboard noise.

Read More